Compare commits
2
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 hanyixuanten |
6648c1c279 | ||
|
hanyixuanten
|
68db99a45c |
No files matched your search
@@ -0,0 +1,34 @@
|
||||
#include<bits/stdc++.h>
|
||||
using namespace std;
|
||||
char s1[1000006], s2[1000006];
|
||||
int n1, n2;
|
||||
int nxt[1000006];
|
||||
void gnext() {
|
||||
for(int i = 2; i <= n2; ++i) {
|
||||
int j = nxt[i - 1];
|
||||
while(j > 0 && s2[j + 1] != s2[i]) j = nxt[j];
|
||||
if(s2[j + 1] == s2[i]) j++;
|
||||
nxt[i] = j;
|
||||
}
|
||||
}
|
||||
void f() {
|
||||
int j = 0;
|
||||
for(int i = 1; i <= n1; ++i) {
|
||||
while(j > 0 && s2[j + 1] != s1[i]) j = nxt[j];
|
||||
if(s2[j + 1] == s1[i]) j++;
|
||||
if(j == n2) {
|
||||
printf("%d\n", i - n2 + 1);
|
||||
j = nxt[j];
|
||||
}
|
||||
}
|
||||
}
|
||||
int main() {
|
||||
scanf("%s%s", s1 + 1, s2 + 1);
|
||||
n1 = strlen(s1 + 1), n2 = strlen(s2 + 1);
|
||||
gnext();
|
||||
f();
|
||||
for(int i = 1; i <= n2; ++i) {
|
||||
printf("%d ", nxt[i]);
|
||||
}
|
||||
return 0;
|
||||
}
|
||||
@@ -0,0 +1,58 @@
|
||||
# P3375 【模板】KMP
|
||||
|
||||
## 题目描述
|
||||
|
||||
给出两个字符串 $s_1$ 和 $s_2$,若 $s_1$ 的区间 $[l, r]$ 子串与 $s_2$ 完全相同,则称 $s_2$ 在 $s_1$ 中出现了,其出现位置为 $l$。
|
||||
现在请你求出 $s_2$ 在 $s_1$ 中所有出现的位置。
|
||||
|
||||
定义一个字符串 $s$ 的 border 为 $s$ 的一个**非 $s$ 本身**的子串 $t$,满足 $t$ 既是 $s$ 的前缀,又是 $s$ 的后缀。
|
||||
对于 $s_2$,你还需要求出对于其每个前缀 $s'$ 的最长 border $t'$ 的长度。
|
||||
|
||||
## 输入格式
|
||||
|
||||
第一行为一个字符串,即为 $s_1$。
|
||||
第二行为一个字符串,即为 $s_2$。
|
||||
|
||||
## 输出格式
|
||||
|
||||
首先输出若干行,每行一个整数,**按从小到大的顺序**输出 $s_2$ 在 $s_1$ 中出现的位置。
|
||||
最后一行输出 $|s_2|$ 个整数,第 $i$ 个整数表示 $s_2$ 的长度为 $i$ 的前缀的最长 border 长度。
|
||||
|
||||
## 输入输出样例 #1
|
||||
|
||||
### 输入 #1
|
||||
|
||||
```
|
||||
ABABABC
|
||||
ABA
|
||||
|
||||
```
|
||||
|
||||
### 输出 #1
|
||||
|
||||
```
|
||||
1
|
||||
3
|
||||
0 0 1
|
||||
|
||||
```
|
||||
|
||||
## 说明/提示
|
||||
|
||||
### 样例 1 解释
|
||||
|
||||
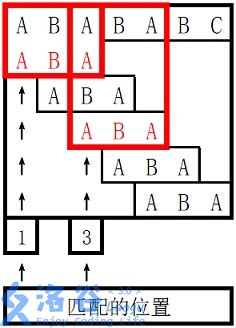。
|
||||
|
||||
对于 $s_2$ 长度为 $3$ 的前缀 `ABA`,字符串 `A` 既是其后缀也是其前缀,且是最长的,因此最长 border 长度为 $1$。
|
||||
|
||||
|
||||
### 数据规模与约定
|
||||
|
||||
**本题采用多测试点捆绑测试,共有 4 个子任务**。
|
||||
|
||||
- Subtask 0(30 points):$|s_1| \leq 15$,$|s_2| \leq 5$。
|
||||
- Subtask 1(40 points):$|s_1| \leq 10^4$,$|s_2| \leq 10^2$。
|
||||
- Subtask 2(30 points):无特殊约定。
|
||||
- Subtask 3(0 points):Hack。
|
||||
|
||||
对于全部的测试点,保证 $1 \leq |s_1|,|s_2| \leq 10^6$,$s_1, s_2$ 中均只含大写英文字母。
|
||||
@@ -0,0 +1,65 @@
|
||||
#include <bits/stdc++.h>
|
||||
using namespace std;
|
||||
int t;
|
||||
int n, q;
|
||||
struct node{
|
||||
vector<node*> child;
|
||||
char c;
|
||||
int cnt = 0;
|
||||
int childsize = 0;
|
||||
};
|
||||
char s[3000005];
|
||||
int len;
|
||||
void add(node *now, int i) {
|
||||
now -> childsize++;
|
||||
if(i == len) {
|
||||
now -> cnt++;
|
||||
return;
|
||||
}
|
||||
// if(now -> c == ' ') {
|
||||
bool flag = 0;
|
||||
for(auto c : now -> child) {
|
||||
if(c -> c == s[i]) {
|
||||
add(c, i + 1);
|
||||
flag = 1;
|
||||
break;
|
||||
}
|
||||
}
|
||||
if(!flag) {
|
||||
node *nc = new node;
|
||||
nc -> c = s[i];
|
||||
now->child.push_back(nc);
|
||||
add(nc, i + 1);
|
||||
}
|
||||
// }
|
||||
}
|
||||
int query(node *now, int i) {
|
||||
if(i == len) {
|
||||
return now -> childsize;
|
||||
}
|
||||
for(auto c : now -> child) {
|
||||
if(c -> c == s[i]) {
|
||||
return query(c, i + 1);
|
||||
}
|
||||
}
|
||||
return 0;
|
||||
}
|
||||
int main() {
|
||||
scanf("%d", &t);
|
||||
while(t--) {
|
||||
node *root = new node;
|
||||
// root -> c=' ';
|
||||
scanf("%d%d", &n, &q);
|
||||
for(int i = 1; i <= n; ++i) {
|
||||
scanf("%s", s + 1);
|
||||
len = strlen(s + 1) + 1;
|
||||
add(root, 1);
|
||||
}
|
||||
for(int i = 1; i <= q; ++i) {
|
||||
scanf("%s", s + 1);
|
||||
len = strlen(s + 1) + 1;
|
||||
printf("%d\n", query(root, 1));
|
||||
}
|
||||
}
|
||||
return 0;
|
||||
}
|
||||
@@ -0,0 +1,71 @@
|
||||
# P8306 【模板】字典树 / Trie
|
||||
|
||||
## 题目描述
|
||||
|
||||
给定 $n$ 个模式串 $s_1, s_2, \dots, s_n$ 和 $q$ 次询问,每次询问给定一个文本串 $t_i$,请回答 $s_1 \sim s_n$ 中有多少个字符串 $s_j$ 满足 $t_i$ 是 $s_j$ 的**前缀**。
|
||||
|
||||
一个字符串 $t$ 是 $s$ 的前缀当且仅当从 $s$ 的末尾删去若干个(可以为 $0$ 个)连续的字符后与 $t$ 相同。
|
||||
|
||||
输入的字符串大小写敏感。例如,字符串 `Fusu` 和字符串 `fusu` 不同。
|
||||
|
||||
## 输入格式
|
||||
|
||||
**本题单测试点内有多组测试数据**。
|
||||
|
||||
输入的第一行是一个整数,表示数据组数 $T$。
|
||||
|
||||
对于每组数据,格式如下:
|
||||
第一行是两个整数,分别表示模式串的个数 $n$ 和询问的个数 $q$。
|
||||
接下来 $n$ 行,每行一个字符串,表示一个模式串。
|
||||
接下来 $q$ 行,每行一个字符串,表示一次询问。
|
||||
|
||||
## 输出格式
|
||||
|
||||
按照输入的顺序依次输出各测试数据的答案。
|
||||
对于每次询问,输出一行一个整数表示答案。
|
||||
|
||||
## 输入输出样例 #1
|
||||
|
||||
### 输入 #1
|
||||
|
||||
```
|
||||
3
|
||||
3 3
|
||||
fusufusu
|
||||
fusu
|
||||
anguei
|
||||
fusu
|
||||
anguei
|
||||
kkksc
|
||||
5 2
|
||||
fusu
|
||||
Fusu
|
||||
AFakeFusu
|
||||
afakefusu
|
||||
fusuisnotfake
|
||||
Fusu
|
||||
fusu
|
||||
1 1
|
||||
998244353
|
||||
9
|
||||
```
|
||||
|
||||
### 输出 #1
|
||||
|
||||
```
|
||||
2
|
||||
1
|
||||
0
|
||||
1
|
||||
2
|
||||
1
|
||||
```
|
||||
|
||||
## 说明/提示
|
||||
|
||||
### 数据规模与约定
|
||||
|
||||
对于全部的测试点,保证 $1 \leq T, n, q\leq 10^5$,且输入字符串的总长度不超过 $3 \times 10^6$。输入的字符串只含大小写字母和数字,且不含空串。
|
||||
|
||||
### 说明
|
||||
std 的 IO 使用的是关闭同步后的 cin/cout,本题不卡常。
|
||||
Reference in new issue
Block a user